

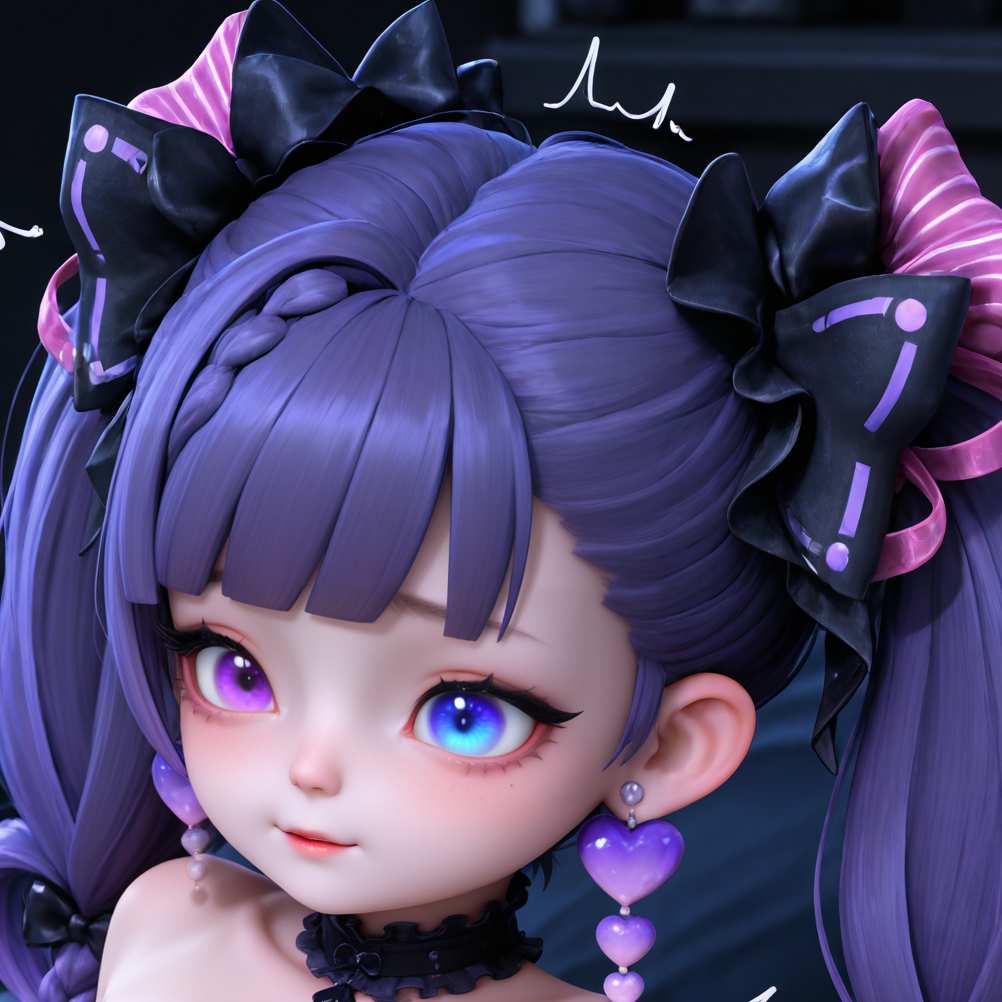
AI Fan Art: Angela, Heart of Kolomi, Out-of-Game Modeling Style (Part 1) 558P+72V+3 Long V Test
US$4.49
-33%US$2.99
Attachment 1
Attachment 2
Data saving: A mistake in the raw image model branching resulted in lower fidelity in hair details and accessories; loading LoRa degraded the art style, and the long video was edited.
1: Segmented keyframe reference: Character features are stable and details are good, but forced action switching and prompt words require a huge amount of work;
2: First frame reference only + action description: The prompt word saves the action transition description, but it is easy to accumulate drift and the effect is poor. Feature locking node will be added later for optimization.
Regarding the images, only the last two added are highly accurate in terms of reproduction. The others have slight deviations in clothing and hair features (the details of the twin ponytails are easily lost, and the hair accessories are separated). The reason is that I mistakenly used the V43 model for extraction but generated the V29 model (a specially tuned, overfitted version, the last generation, used for converting 2D characters from the NETA series to realism; I forgot to switch). Since they are from the same series of fine-tuning, the difference lies in the style difference between 2D and realistic textures. This art style doesn't differ much when loading LoRa, so I didn't notice it. When setting up the workflow, I had to run over 900 images, and only when filtering did I see the exaggerated LoRa style degradation (images after 325) and realize the model was wrong. I temporarily ran a correct version. Please choose carefully when looking at the preview package. There will be a second part (part 2) later, which will supplement some clothing reproduction details.
After several days of dedicated work, the V team finally managed to build two usable infinitely long V processes.
One approach uses keyframe references for each segment, offering good detail but forcing action transitions. The advantage is stable features, but the downside is the potential for strange actions during transitions, and the cue words... Each segment requires at least 2500 cue words, totaling 35,000+ for 12 segments – a nightmare! Furthermore, it requires writing transition cue words, which is difficult for even a highly accurate inference model, and inference is also limited for small-scale models. Another approach uses the first frame reference, providing only action descriptions for the remaining frames. While this is possible with just the first frame, H3 cue words are too difficult to write. Having reference actions allows the inference model to help write them, which you can then refine yourself, making things slightly better. Transitional actions can be omitted. This approach currently doesn't perform well; we'll try adding a feature-locked full-process node later. Ultimately, we'll only optimize one approach.
Based on testing with several characters, multi-keyframe rendering performs better. Another drawback is my weak scriptwriting ability; I can't even write good dialogue. If the raw image workflow could be modified to incorporate contextual relationships with multi-keyframe rendering, the performance would be fantastic. However, I've tried many methods but haven't been able to generate satisfactory contextual content directly without a skeleton map. SDXL, relying solely on tags, struggles to smoothly generate contextual content. StoryDiffusion also can't handle very long sequences. My own local model for generating plot cues didn't work well either. I'll try first creating the video, then extracting frames to retrieve the motion and regenerating the video, but that would increase the time commitment, which is a bit of a headache. With the current H3 workflow, I basically can't do LTX videos anymore; a 12-segment relay takes longer than a 25-segment LTX short video with dual audio. I also need to prepare a bunch of prompts, like writing a thesis. Recent updates also include some LTX videos. Because I accumulated a lot while developing workflows, I won't include them by default anymore. If you'd like to see them added, let me know and I'll add them, but only a few at a time based on your needs. And unlike before, I won't run two rounds to produce two similar videos; otherwise, the time required for the same package would almost double, and I wouldn't have enough time to allocate it.
Preview package: https://www.fansky.co/shoujikong/210
Preview of P: https://www.pixiv.net/artworks/151824632